Features
See it before
you download it.
Every screenshot and clip on this page is London5 itself, running on a MacBook Pro with an M5 Pro chip. The prices and the news are live, and the AI answering is a model running on that same Mac.
Conversation
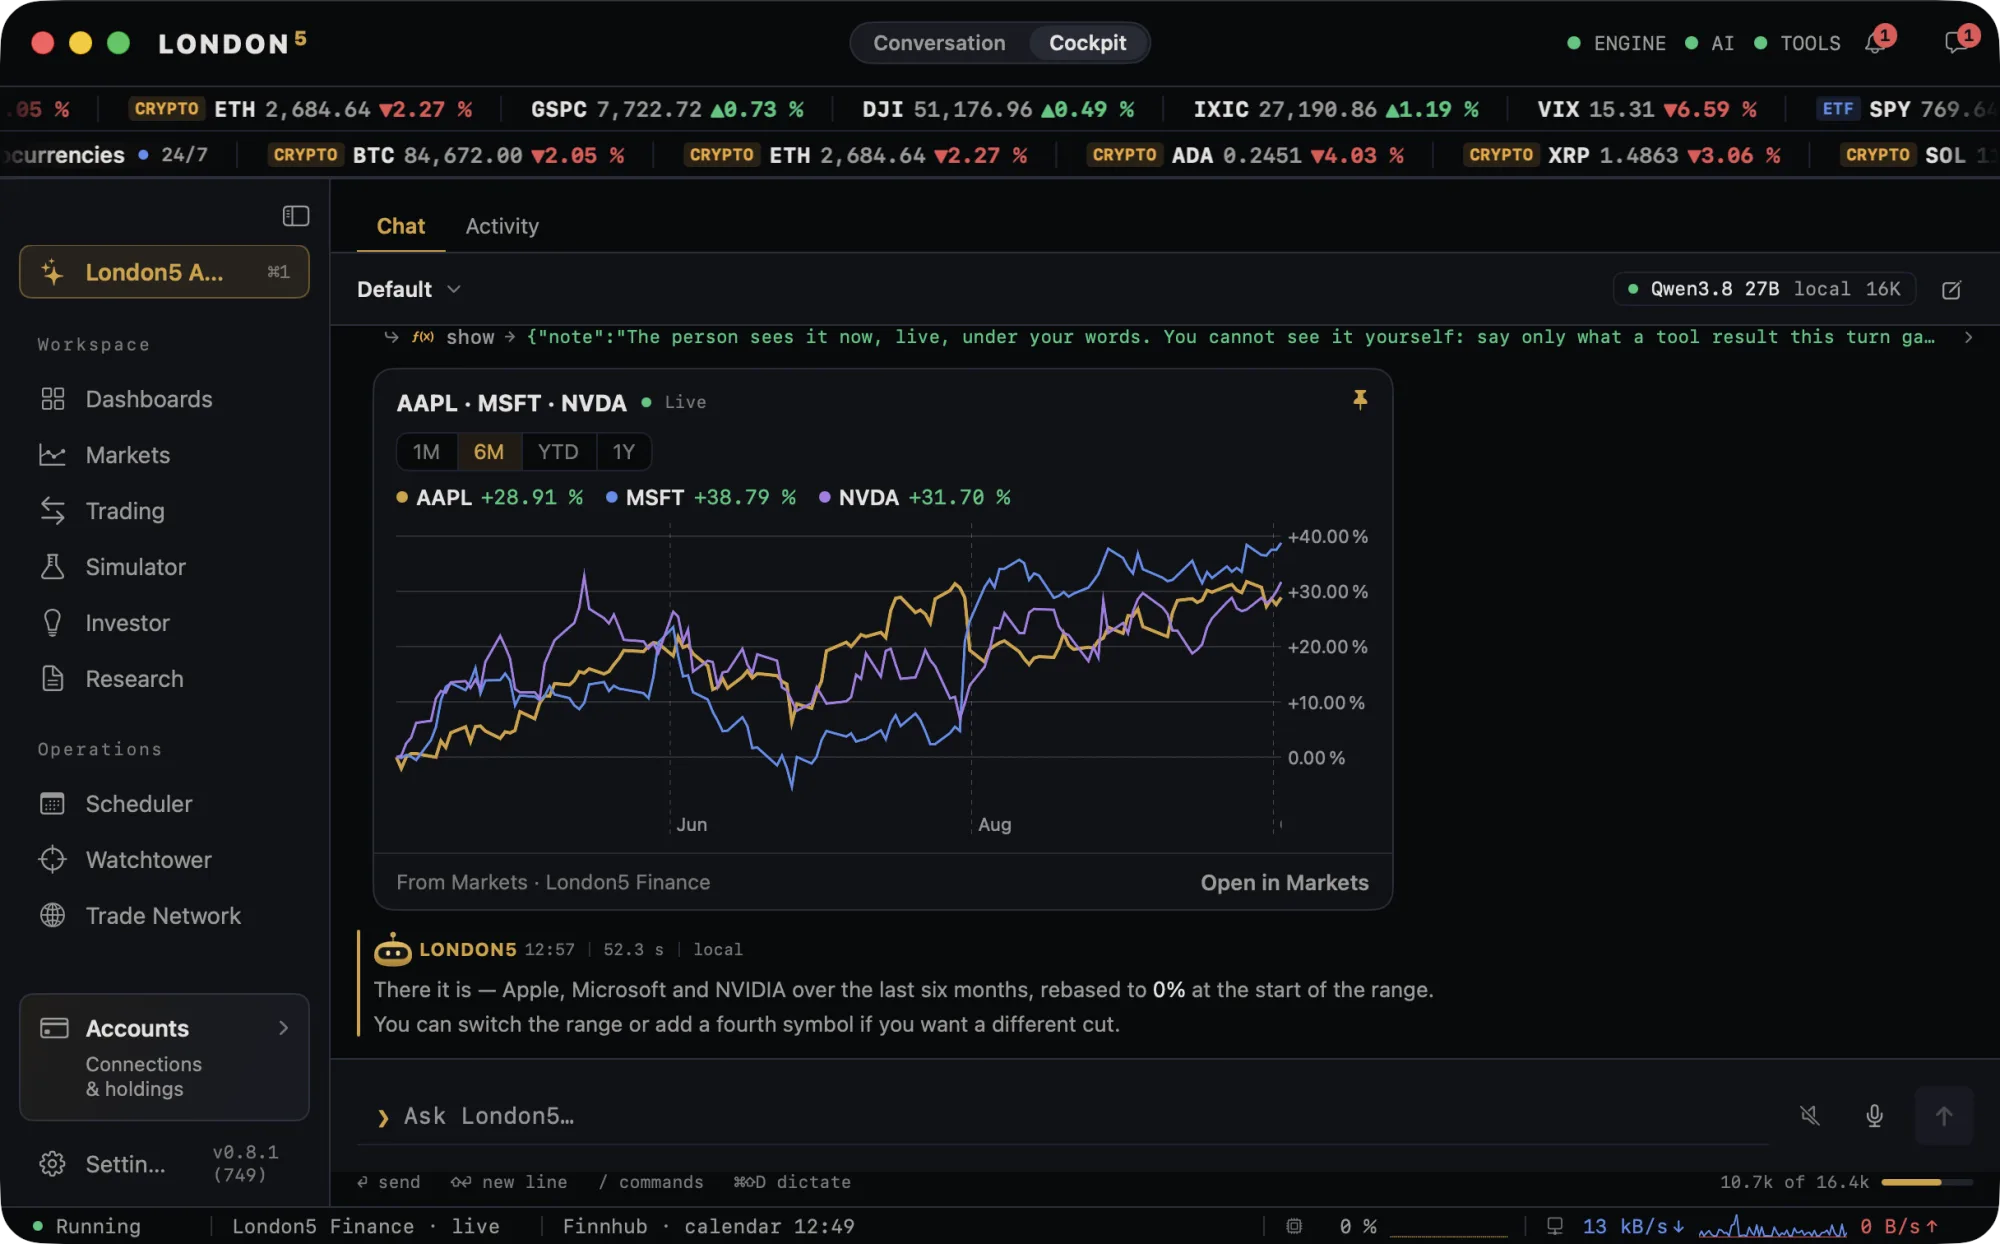
Ask in plain words.
Get the chart, not a paragraph.
Talk to London5 the way you would to a colleague. Pip, your sidekick, reads what it needs, then pushes the chart, the table or the source into the conversation, where you can check it.
Try it here. A working model of the app, running in your browser on a simulated market: pick a suggestion or type, hover a chart, change its range, pin it to your board, or switch to Cockpit at the top.
News & Feeds
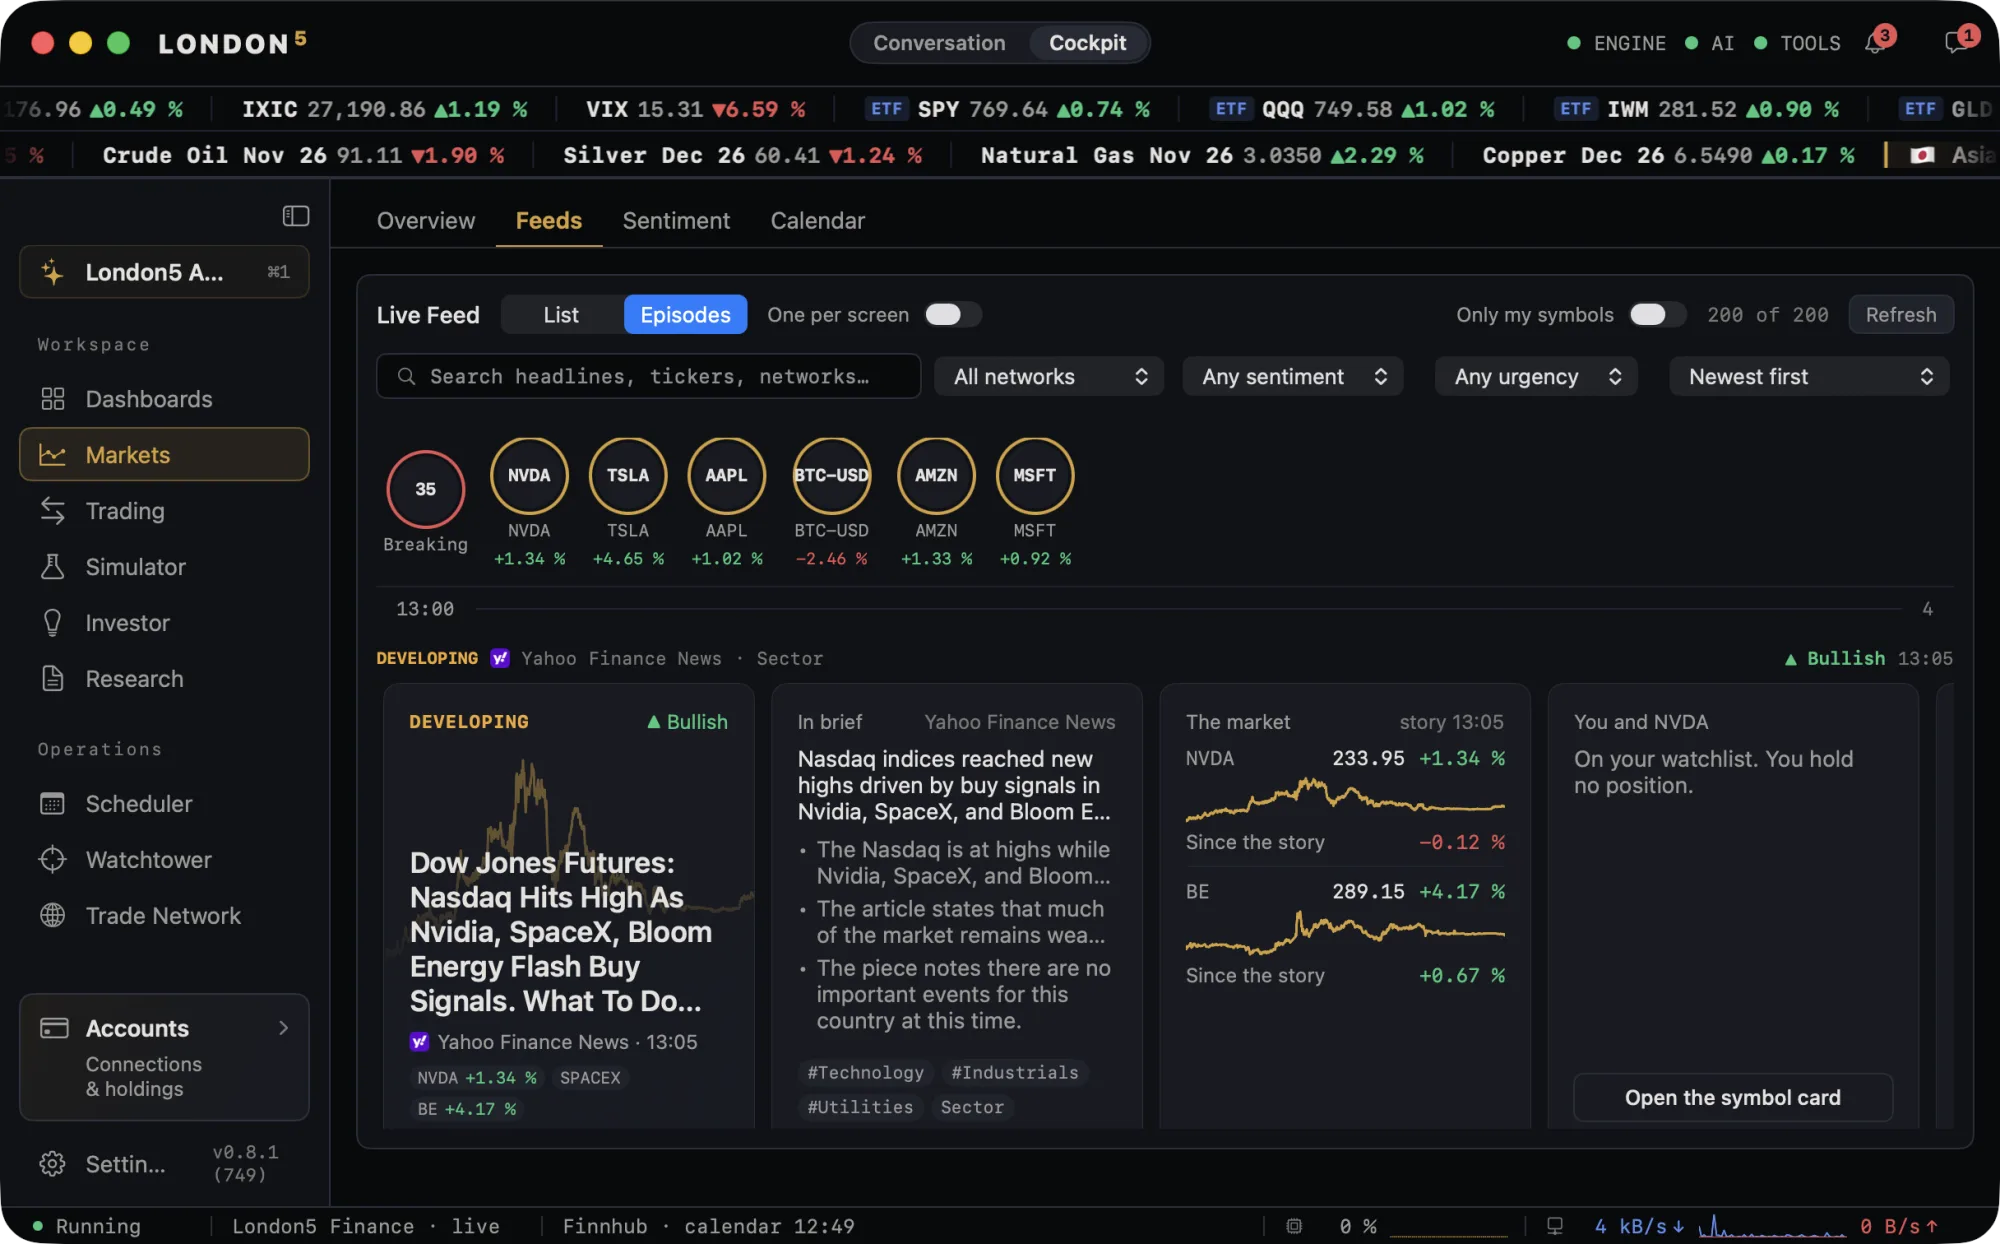
Every story that moves
your markets, sorted.
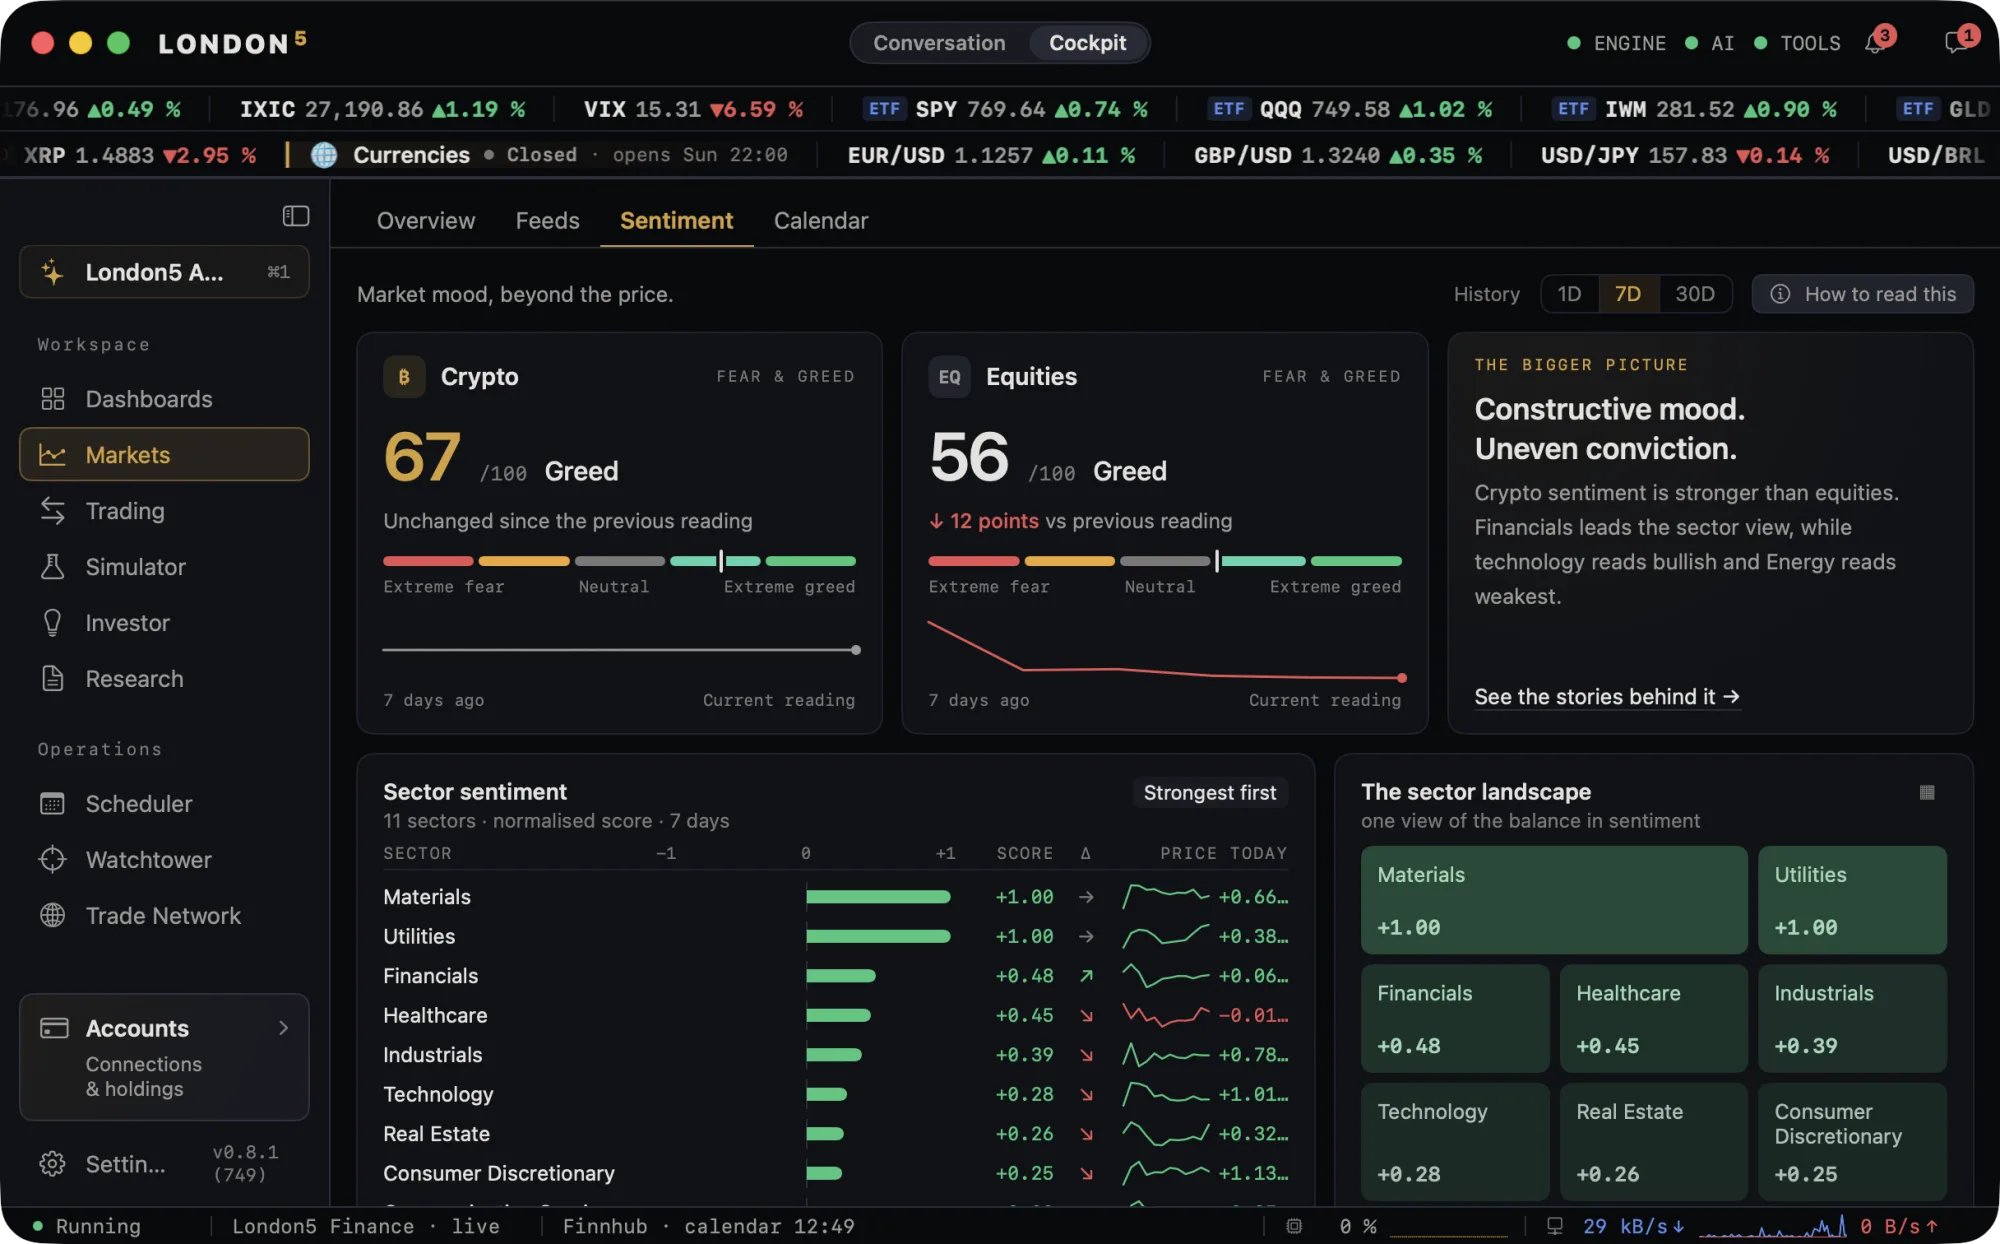
London5 reads the wires and the filings as they land, tags each story with the markets it touches and how it leans, and keeps the ones about your symbols on top. Tap a number to see what each part does.
Dashboards
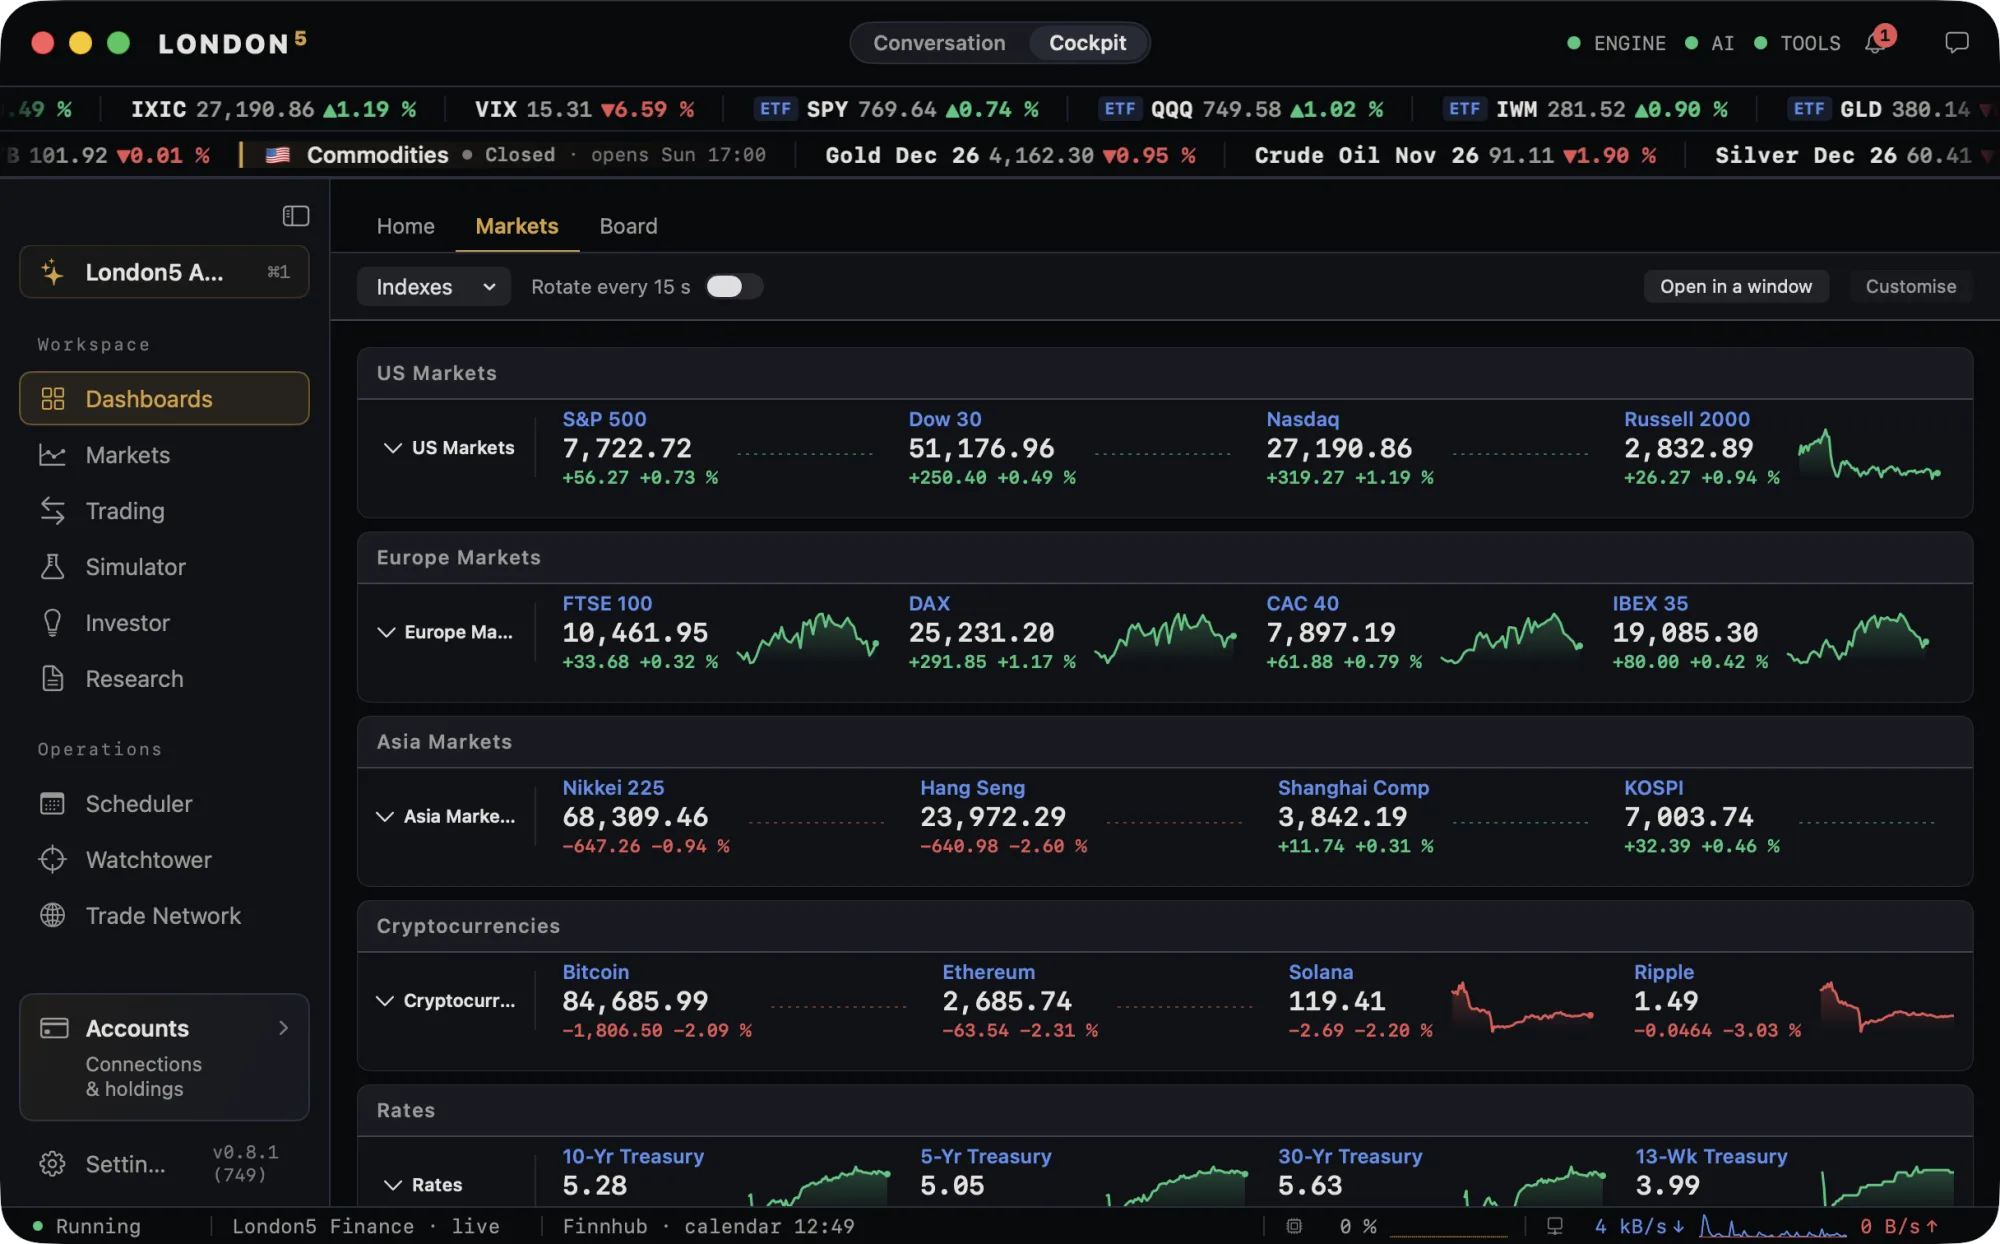
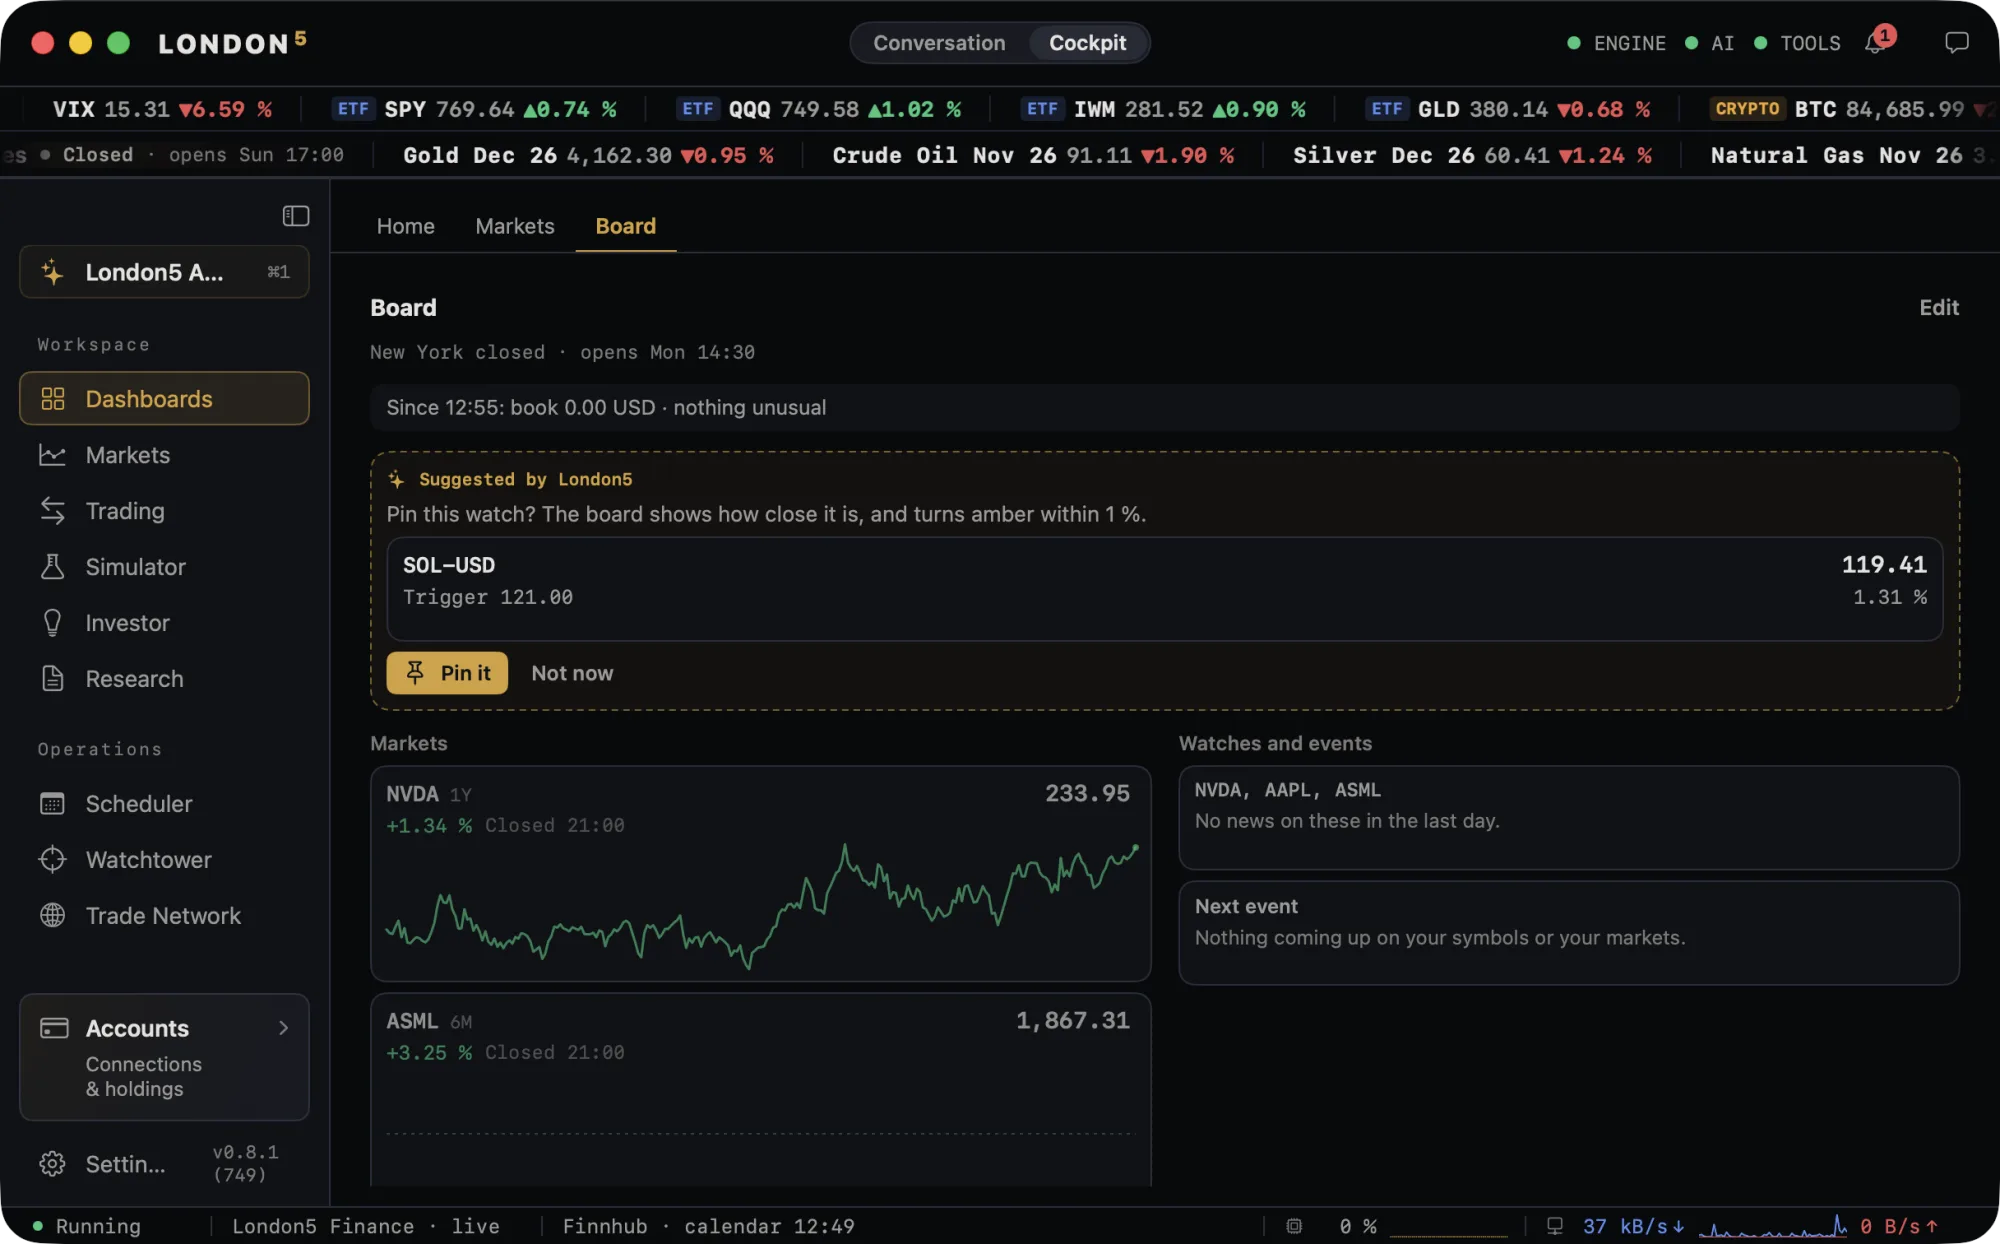
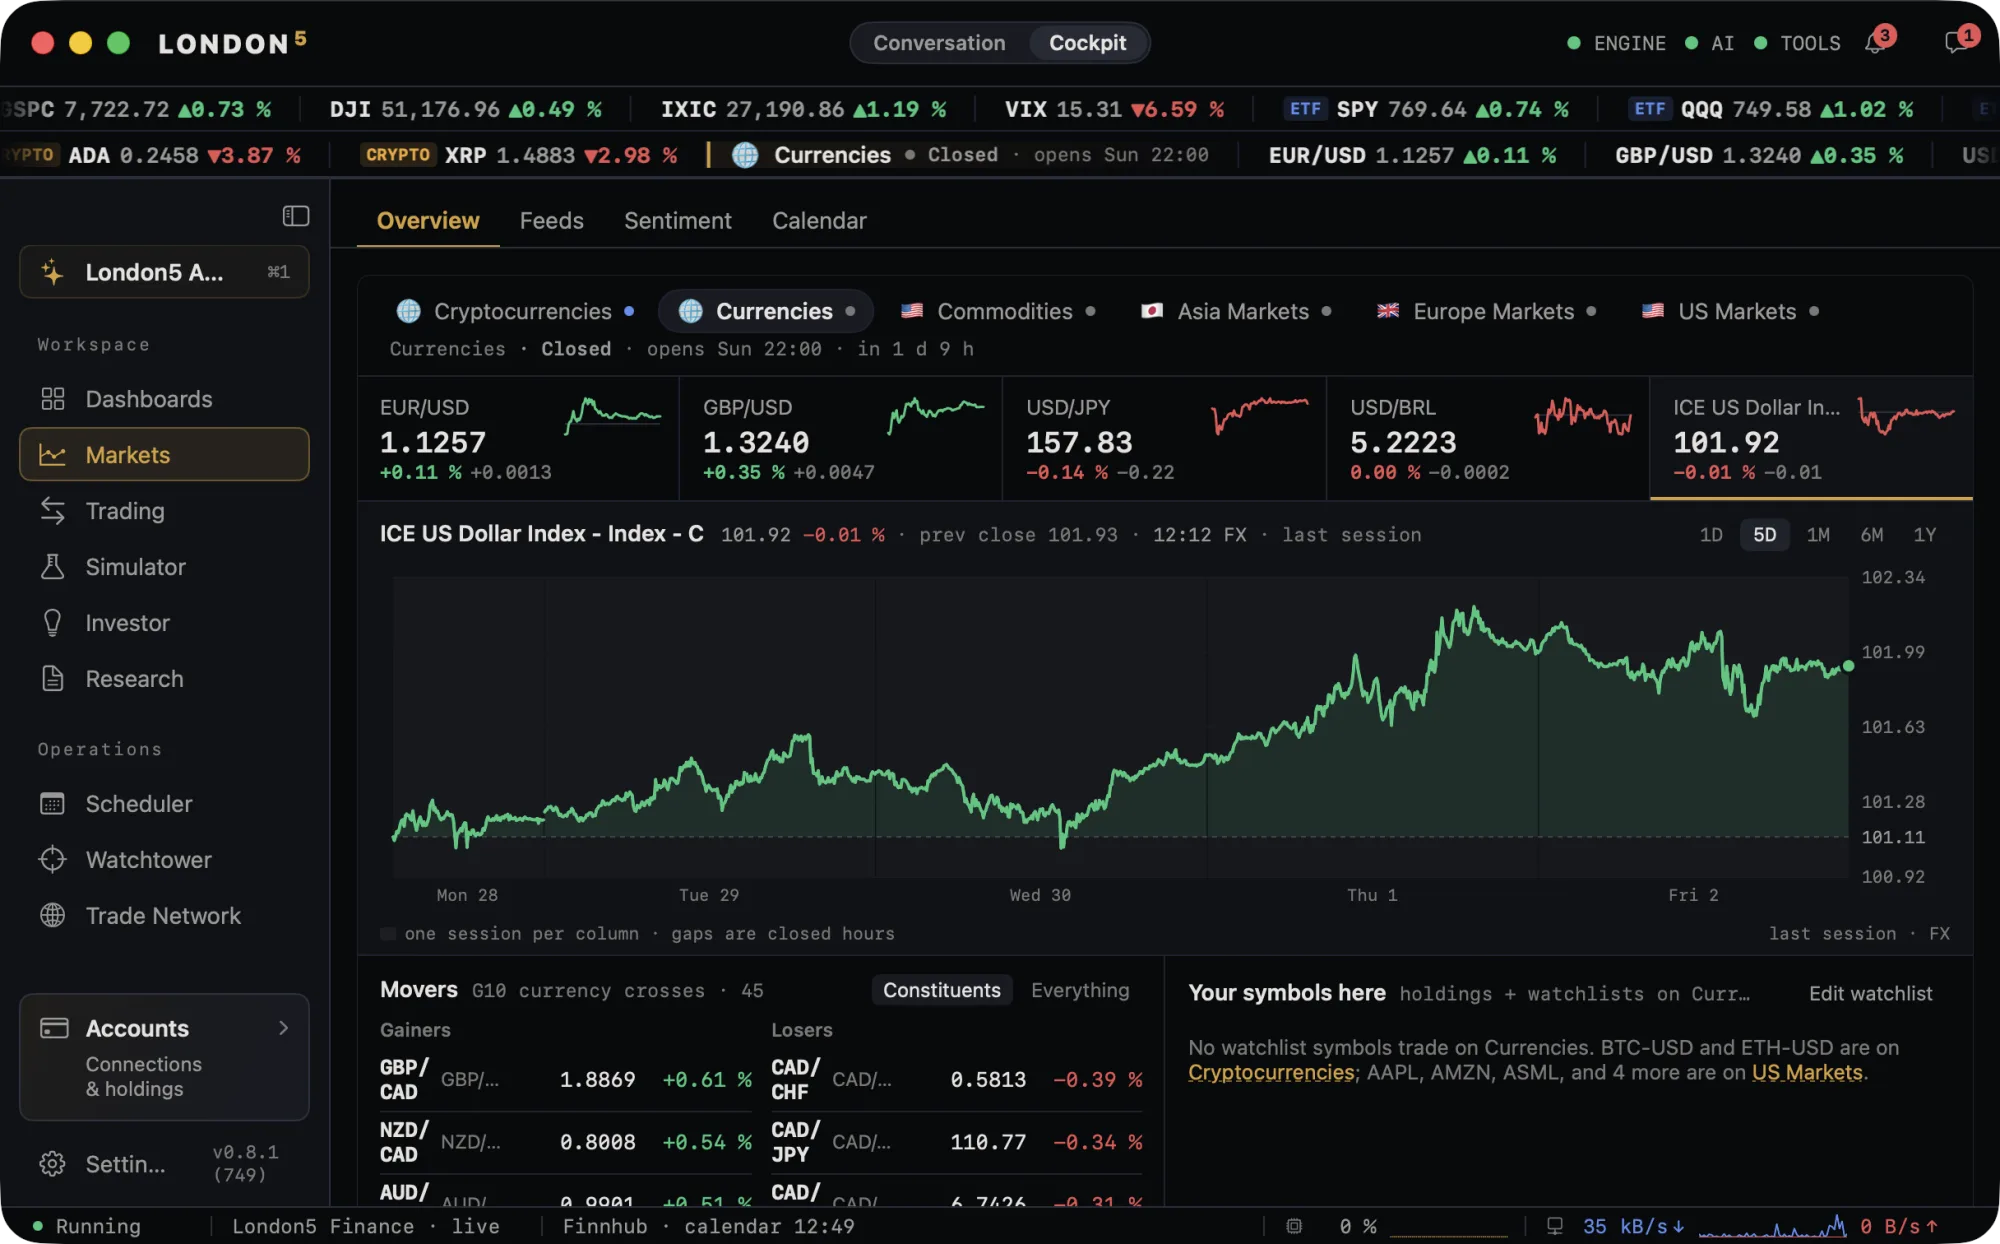
Many charts.
One glance.
Build boards of charts and tiles for the markets you follow, and switch between them. Every tile stays live while the market is open.
Research New version coming
Research that shows
where every finding comes from.
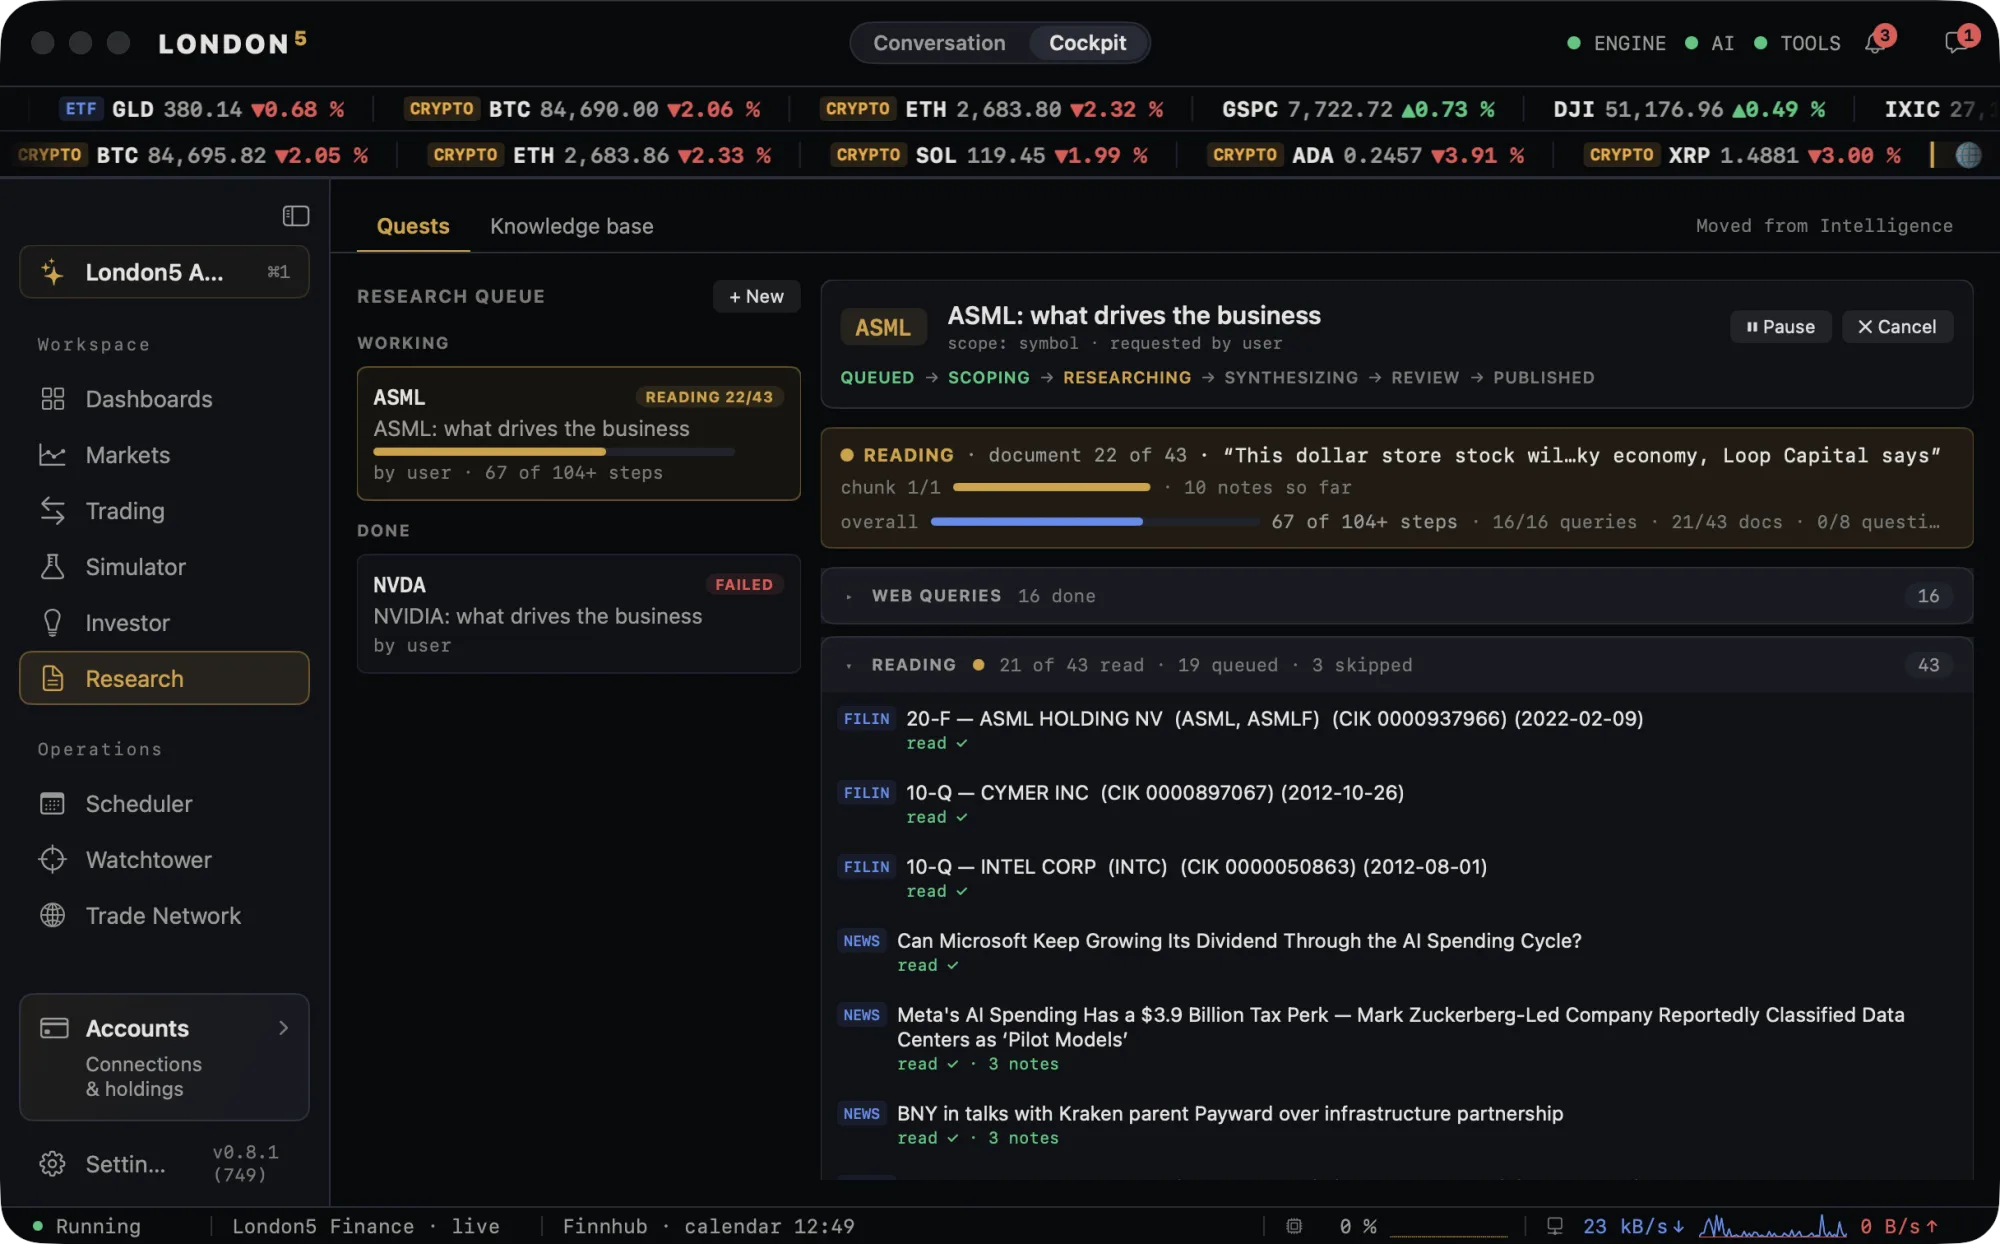
Ask a question about a company and London5 reads the reports, the calls and the news, and writes up what it found, with each finding linked to its source.
Simulator
Six strategies. Real past prices.
All on paper.
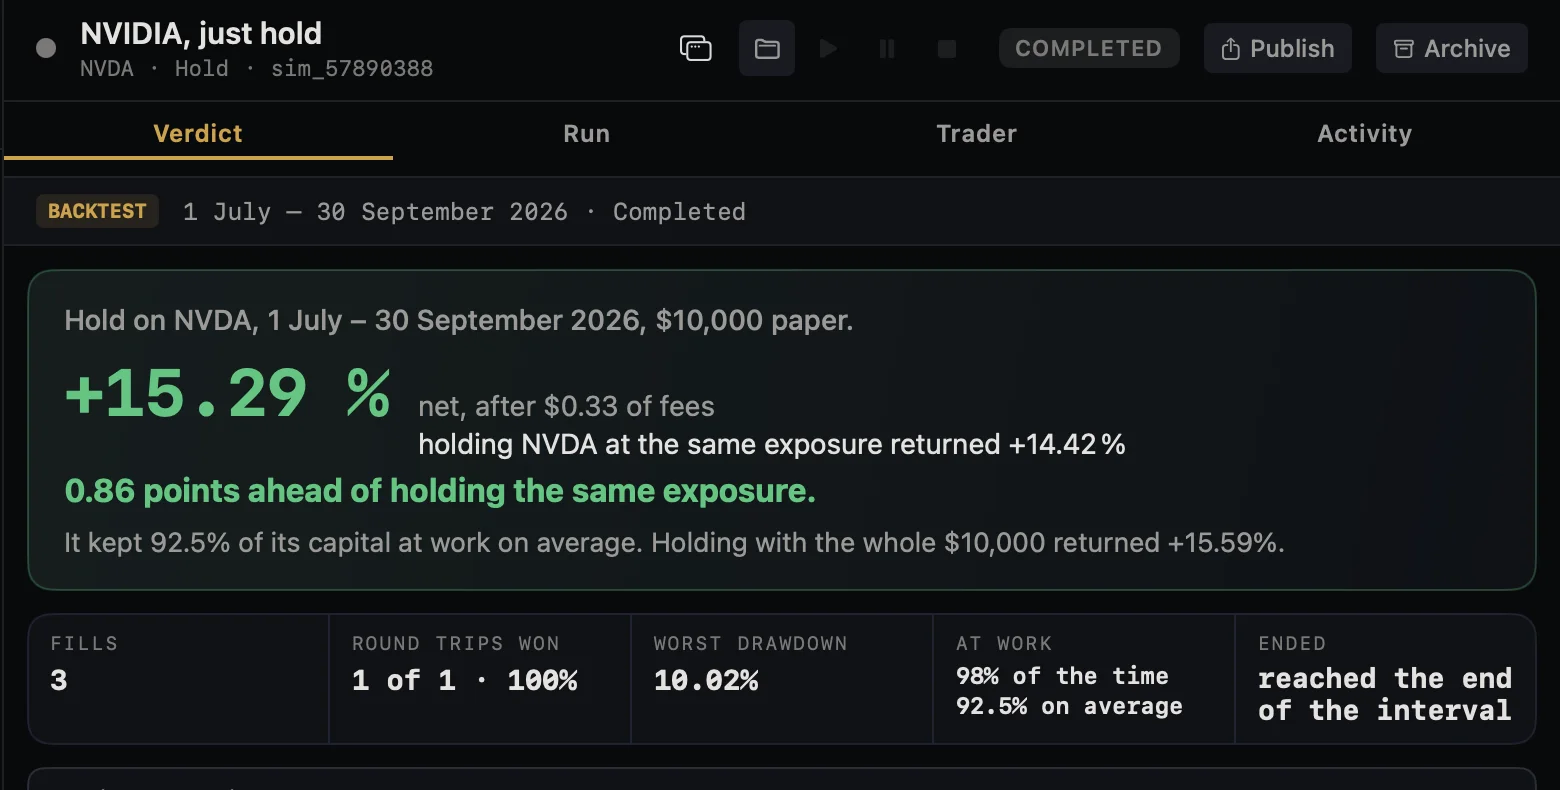
Before you put a strategy to work, run it over real past prices with paper money and see what it would have done: the return, the fees, the worst drop it would have made you sit through, and how it compares with simply holding.2
NVIDIA, just hold
Buy once, hold to the end.
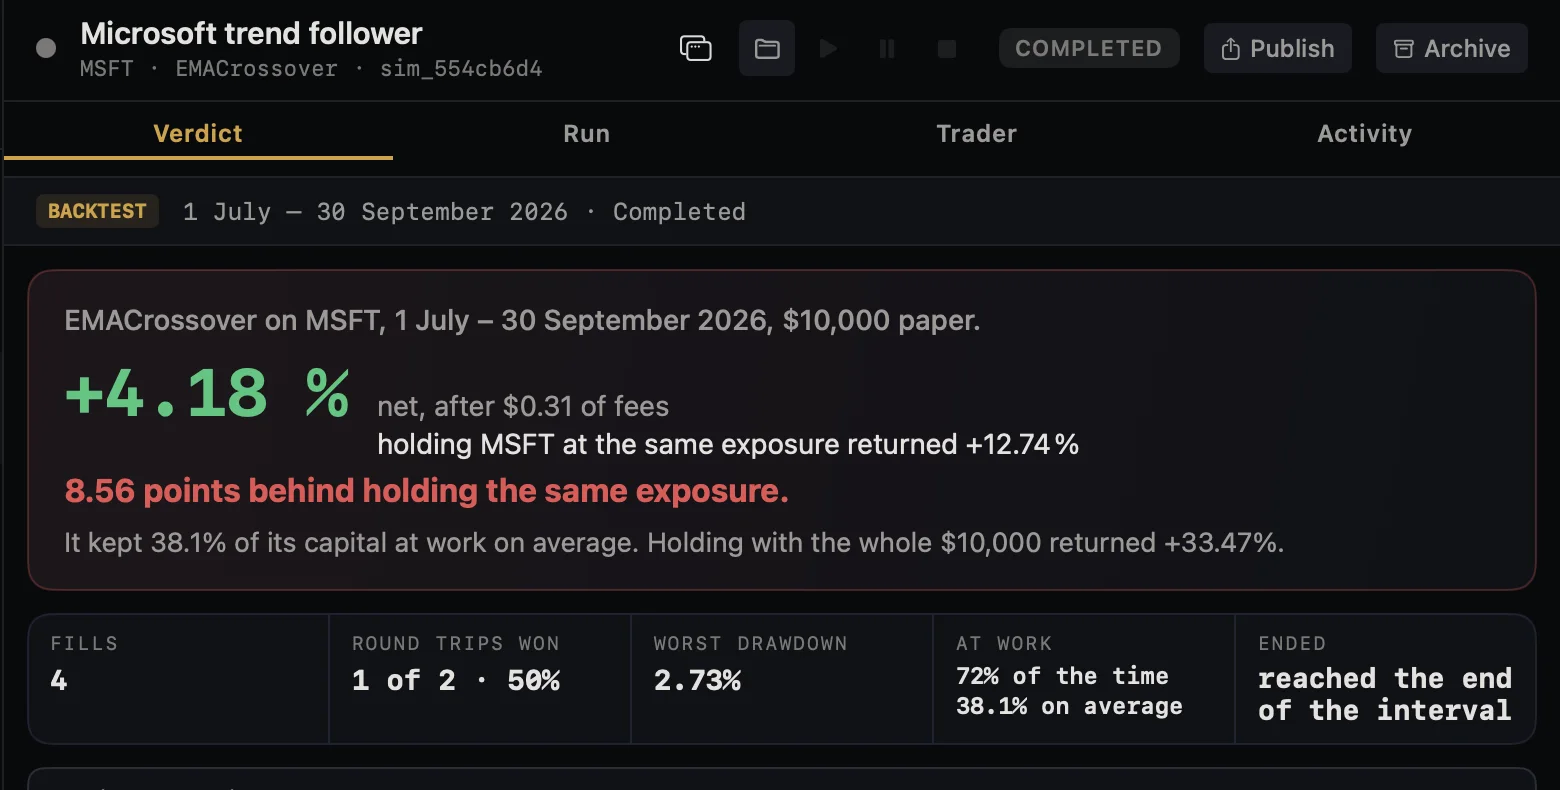
Microsoft trend follower
Buy when the 10-day average rises through the 30-day; sell when it falls back.
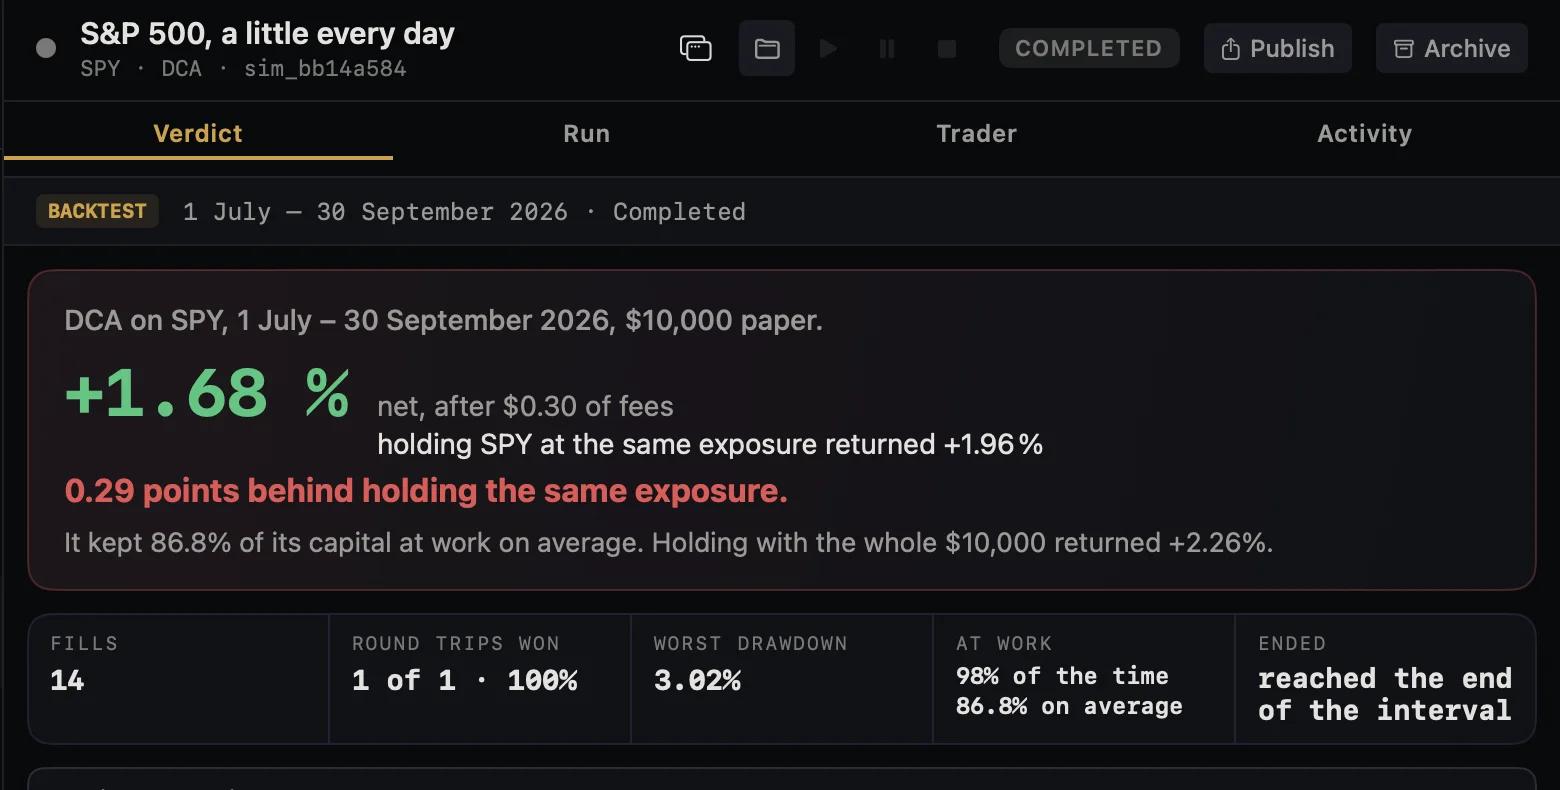
S&P 500, a little every day
Buy $100 of the S&P 500 fund on a daily schedule.
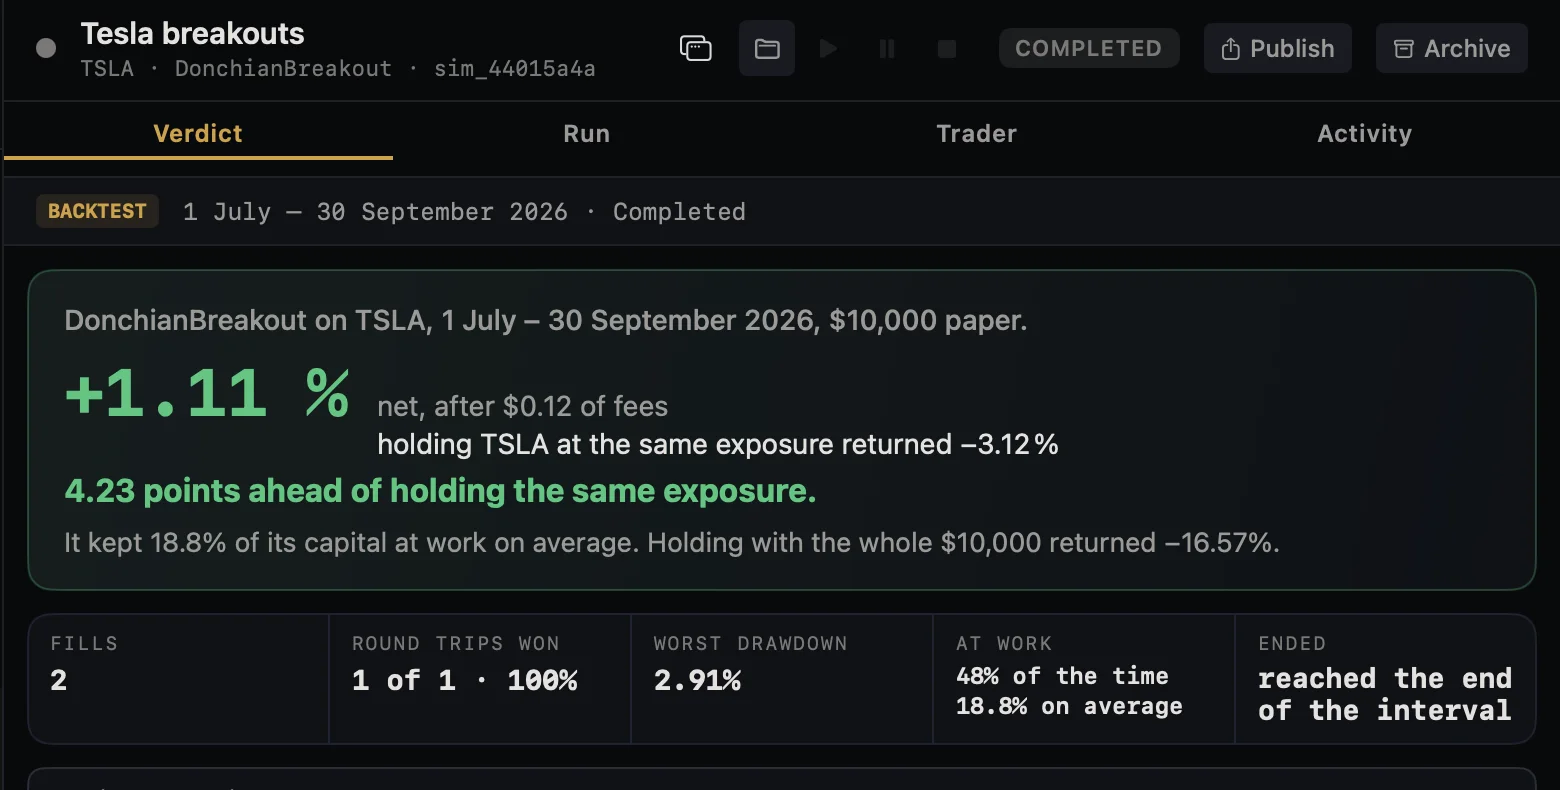
Tesla breakouts
Buy when Tesla closes above its 15-day high; exit on a volatility stop.
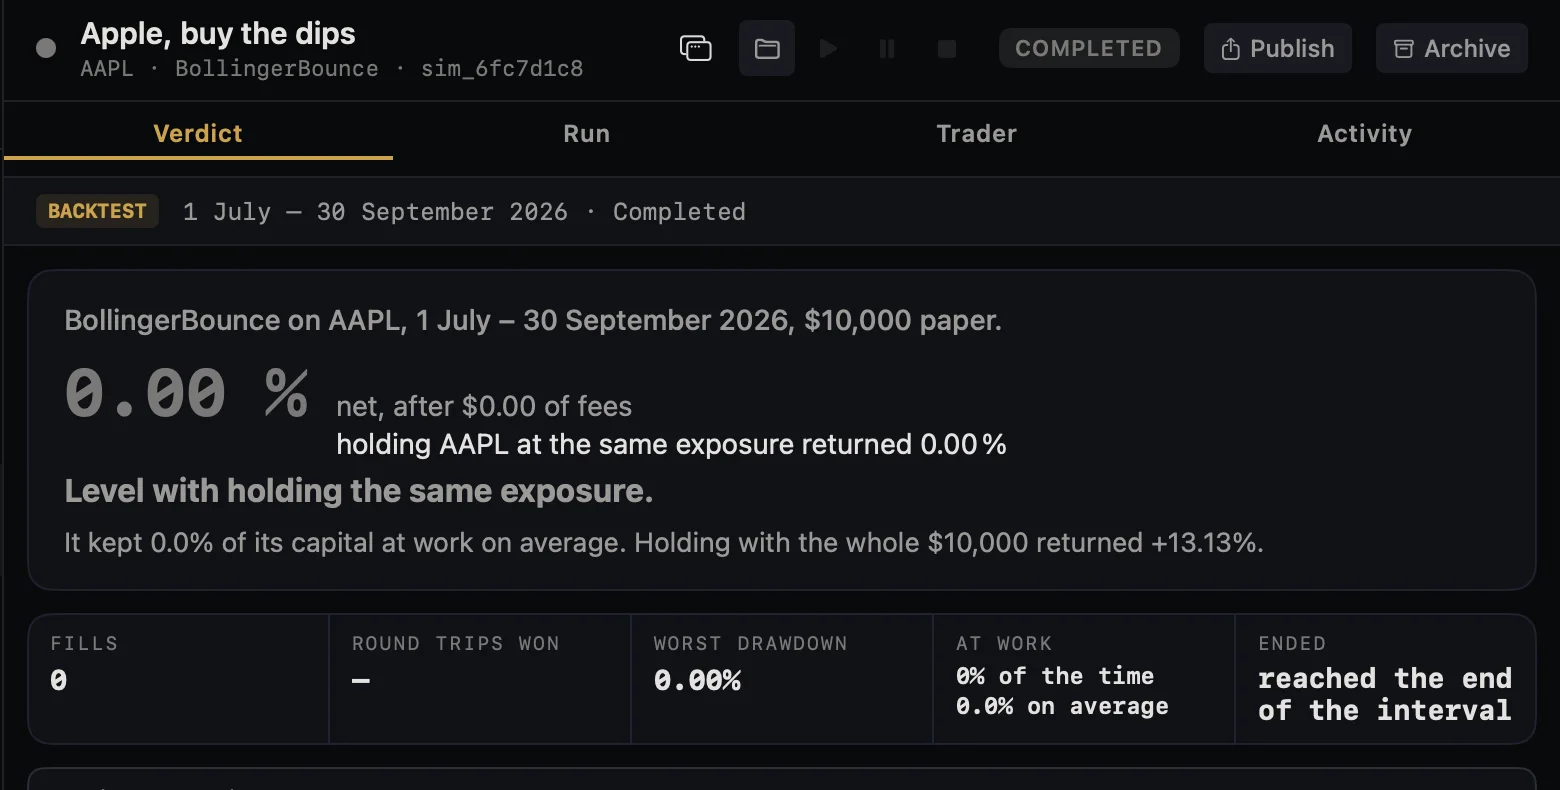
Apple, buy the dips
Buy when Apple closes under its lower Bollinger band.
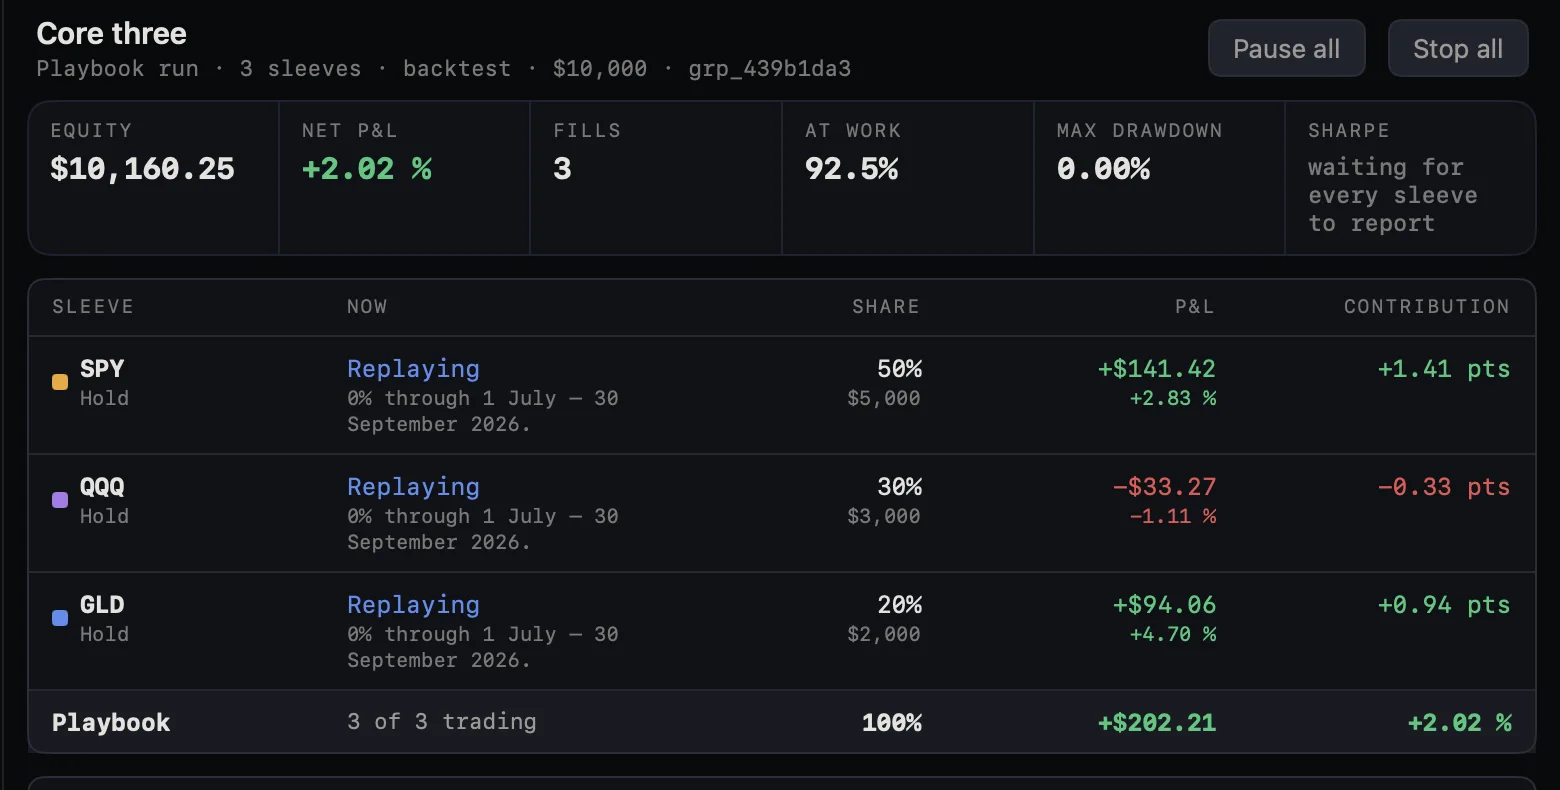
Core three
A playbook: S&P 500 50%, Nasdaq 100 30%, gold 20%, held.
| Strategy | Return | Worst drop | Orders | Holding the whole $10,000 |
|---|---|---|---|---|
| NVIDIA, just hold | +15.3% | 10.0% | 3 | +15.6% |
| Microsoft trend follower | +4.2% | 2.7% | 4 | +33.5% |
| S&P 500, a little every day | +1.7% | 3.0% | 14 | +2.3% |
| Tesla breakouts | +1.1% | 2.9% | 2 | −16.6% |
| Apple, buy the dips | 0.0% | 0.0% | 0 | +13.1% |
| Core three | +2.0% | — | 3 | — |
Paper capital on past daily prices, 1 July – 30 September 2026, $10,000 each. A result on past prices doesn't tell you what comes next, and it isn't a recommendation.
Watches and alerts
Set it,
and get on with your day.
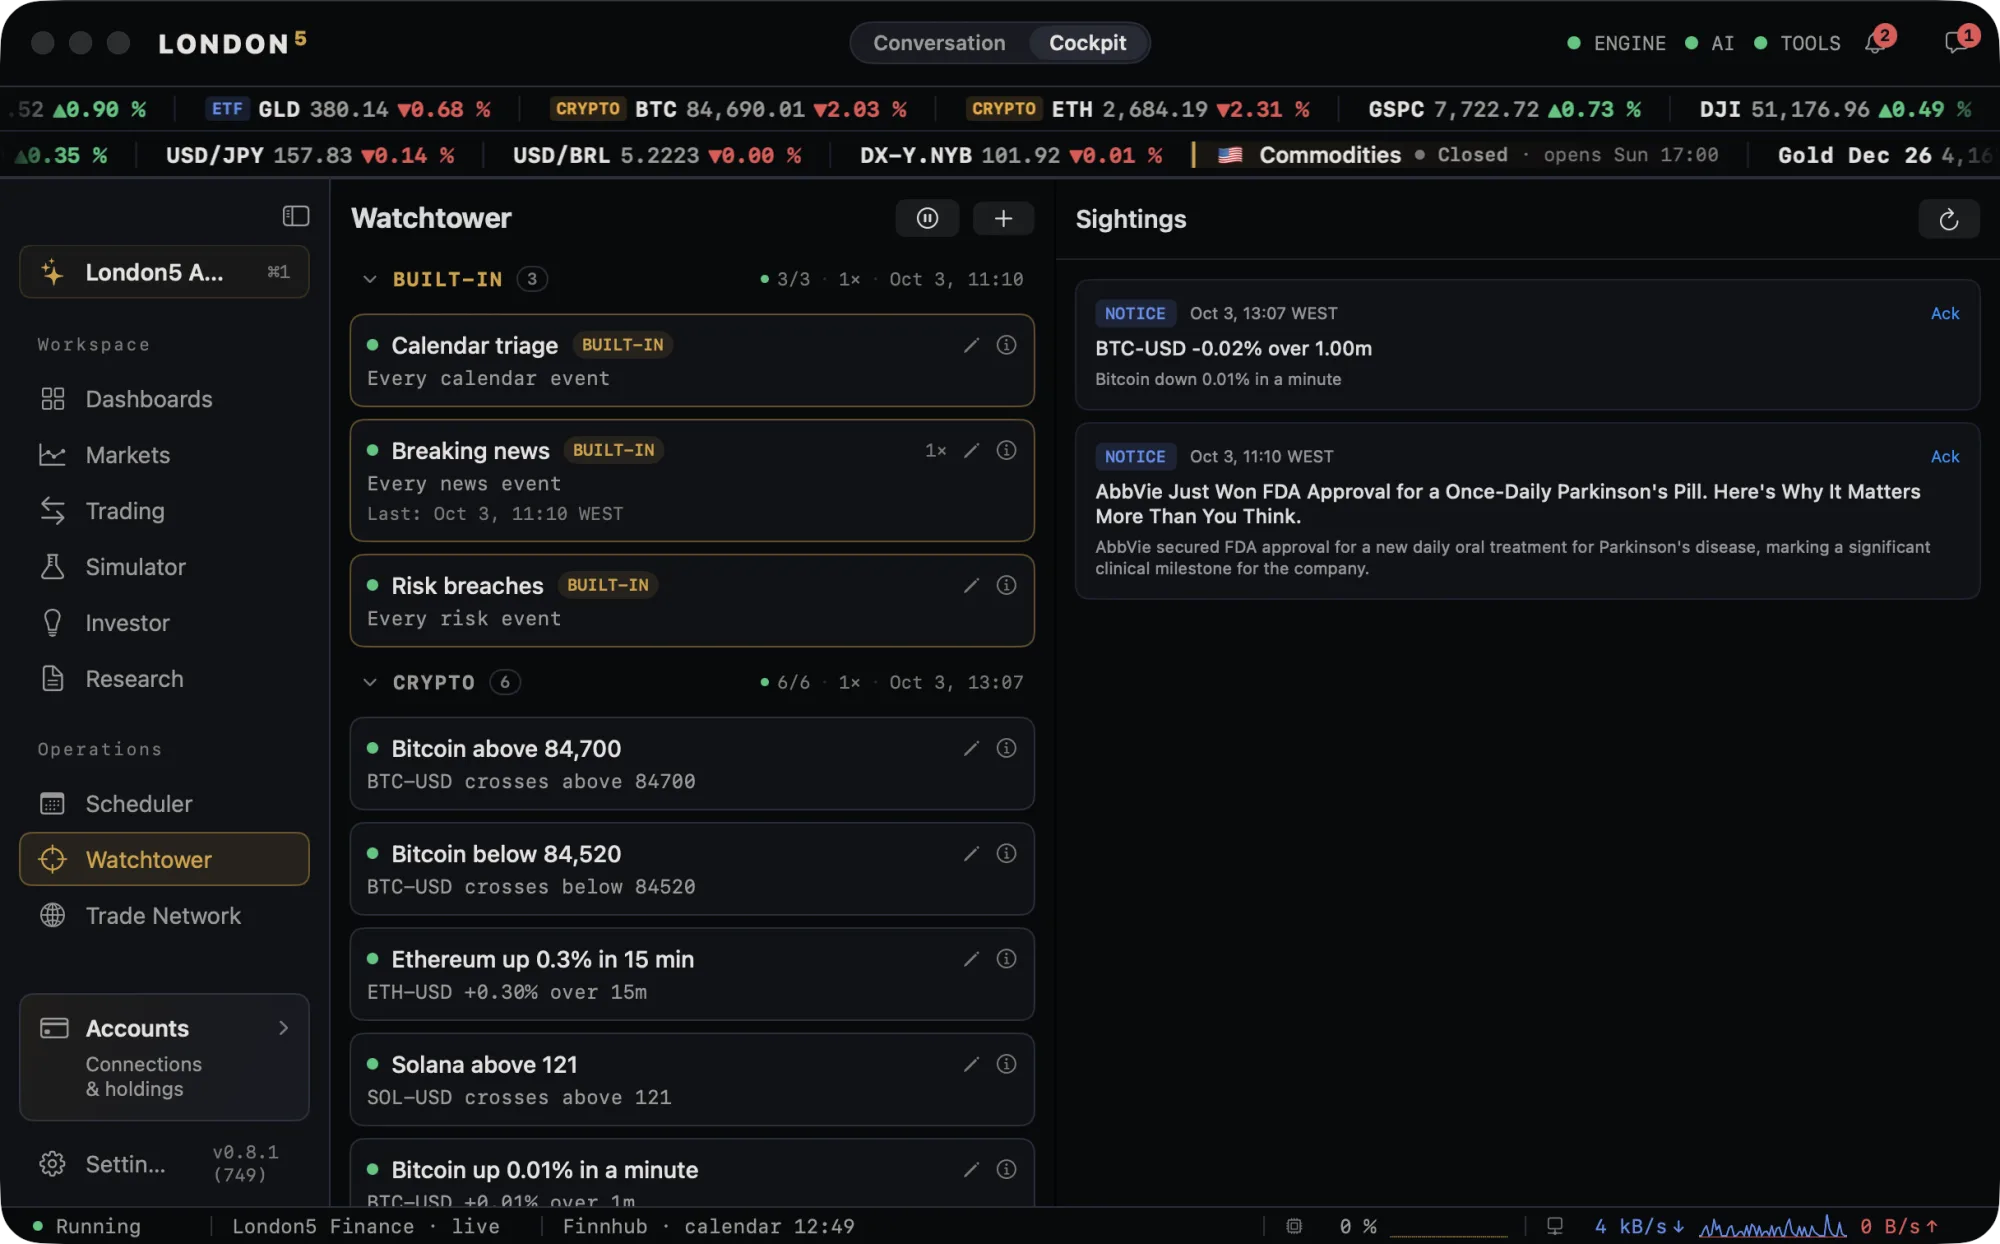
Tell London5 what to watch for, a price, a move, a story, and it keeps watching while your Mac stays on. When something happens it tells you, with what changed next to it. A watch only tells you; it never acts.
// under the hood
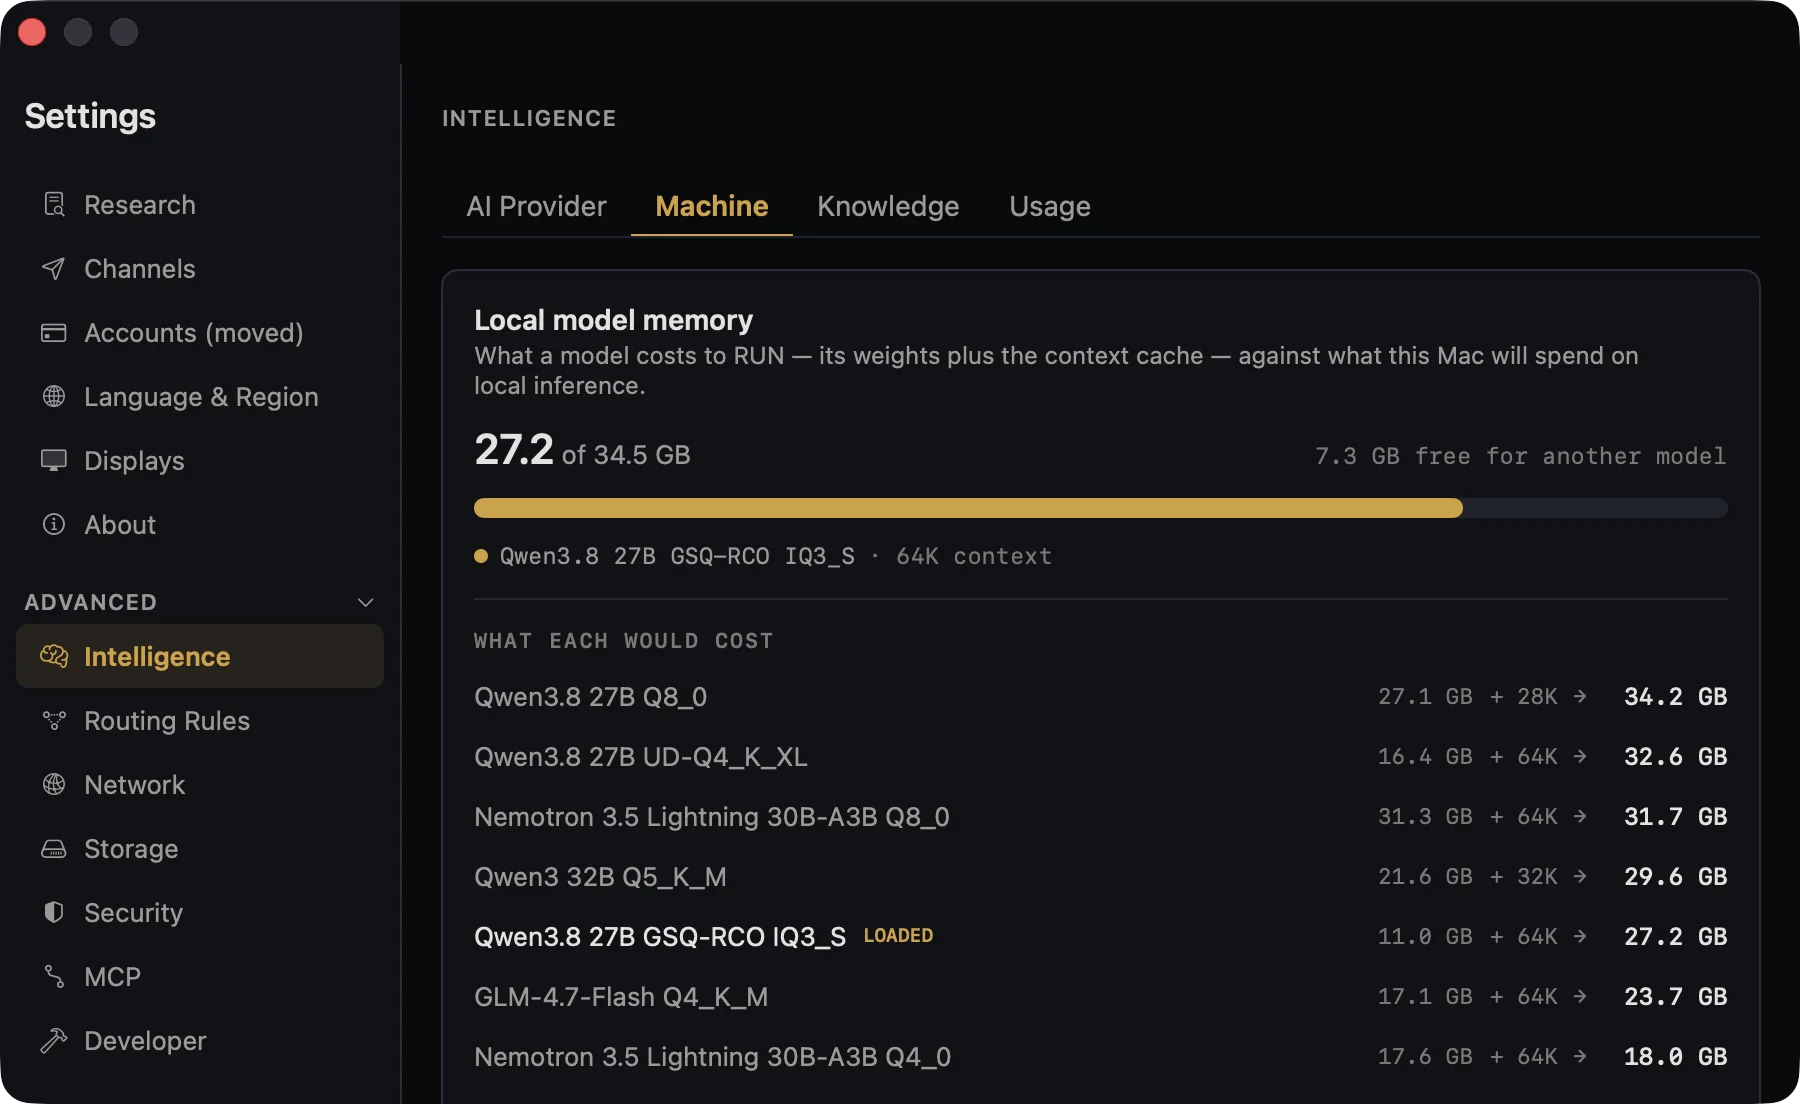
The AI runs on this Mac.
Here are its numbers.
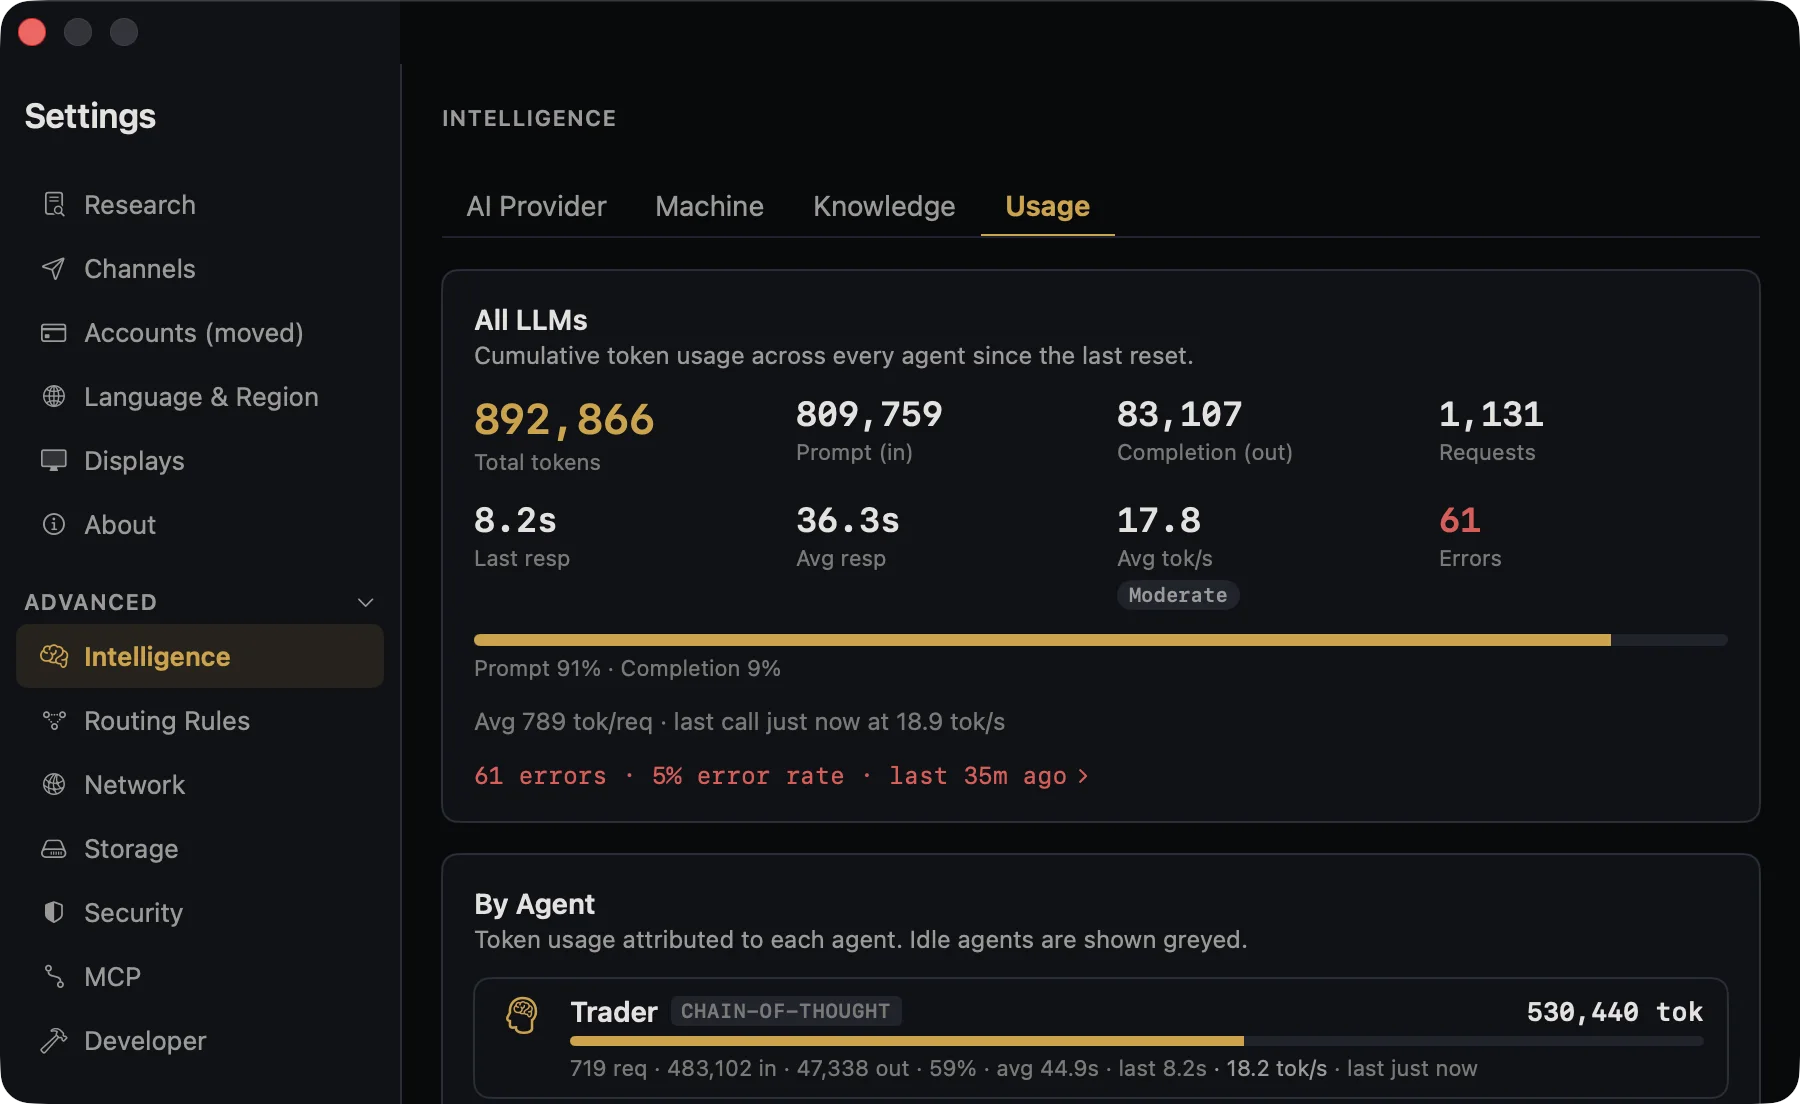
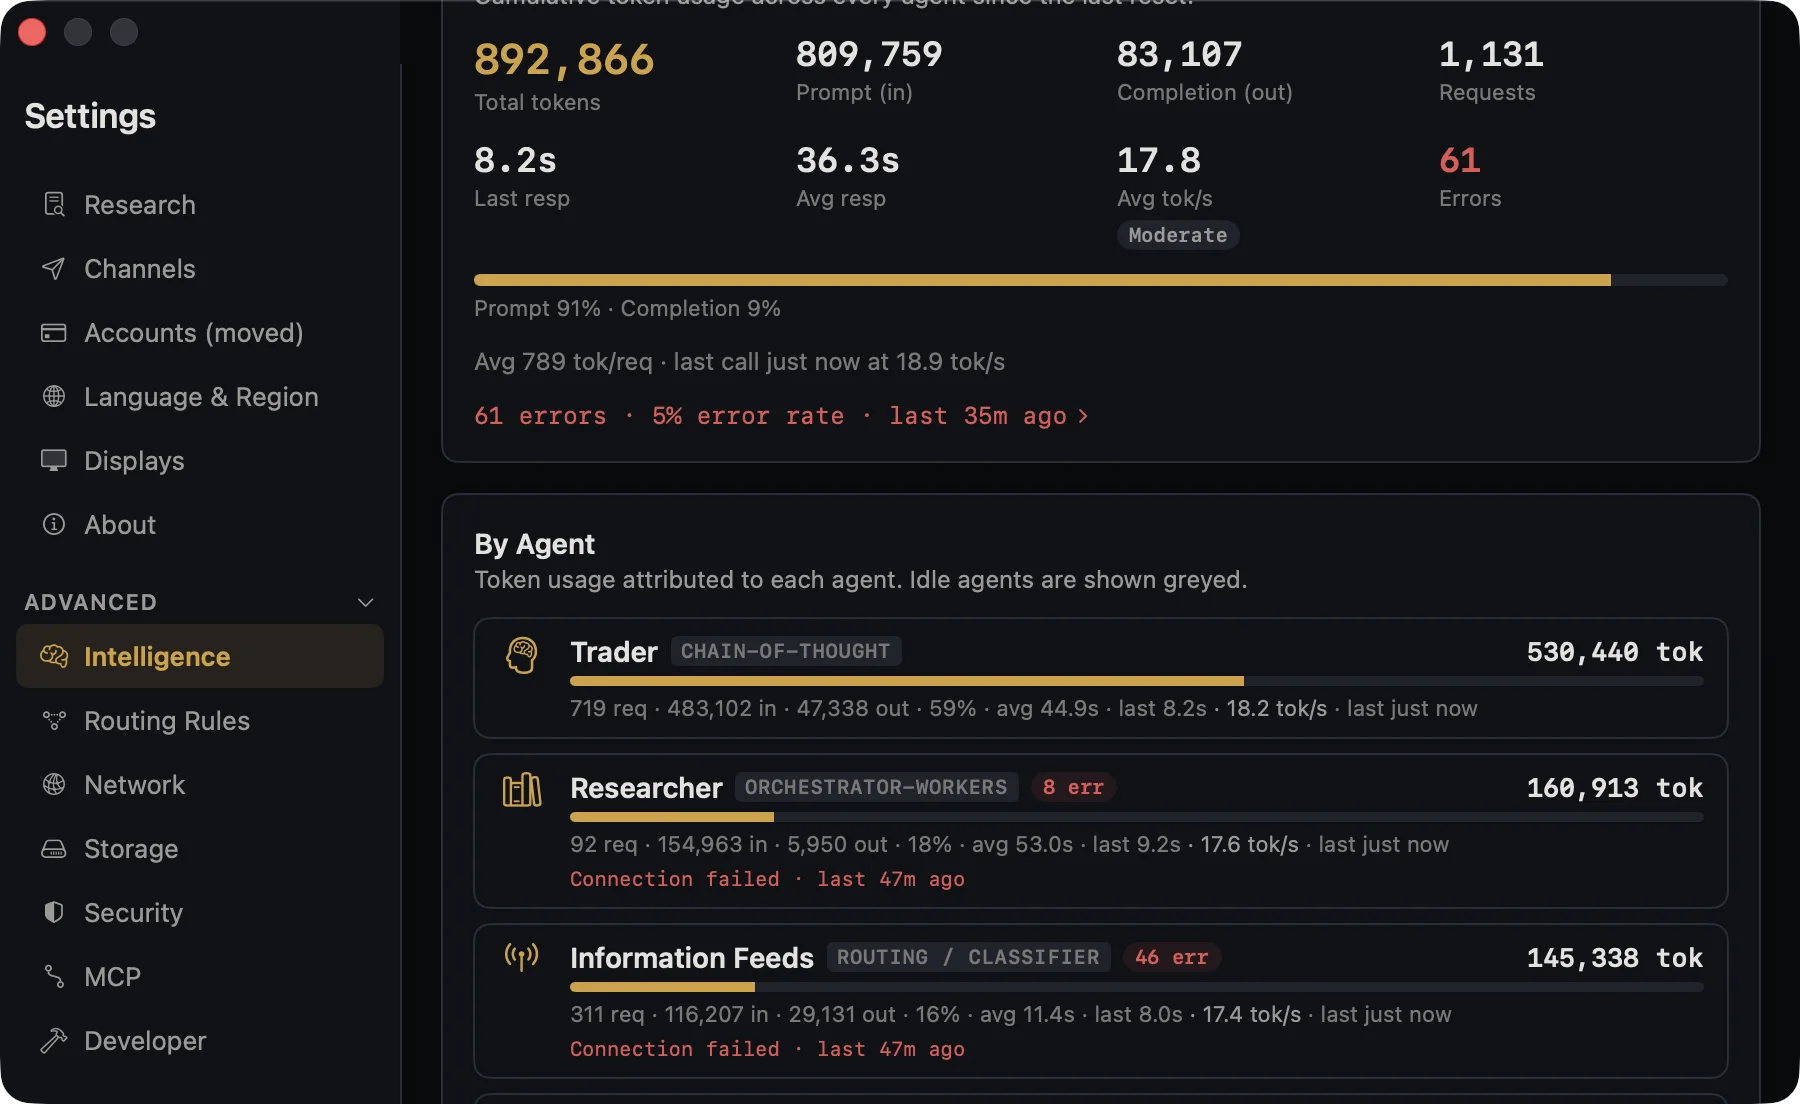
For the curious: London5 measures every model call it makes, how many tokens, how fast, from which agent, and shows it under Settings → Intelligence → Usage. These are the numbers from the session that made this page.
- Machine
- MacBook Pro · Apple M5 Pro
- Memory
- 48 GB unified · 38 GB for the GPU
- Model
- Qwen3.8 27B · 3-bit · 11 GB
- Licence
- Apache 2.0, open weights
- Context
- 16,384 tokens · 4 slots
- Writing speed
- 17.8 tokens/s
- Reading speed
- 220–360 tokens/s
- This session
- 1,131 requests · 892,866 tokens
- AI bill
- €0.00
Measured on 3 October 2026 while the news classifier, a research run and up to eight simulations shared the model. One chat turn read 10,516 tokens of context in 36 s and wrote its answer at 10.5 tokens/s.
# llama-server, started by London5 · Qwen3.8 27B GSQ-RCO IQ3_S
  - MTL0    : Apple M5 Pro (38338 MiB, 38338 MiB free)
llama_context: n_ctx_seq (16384) < n_ctx_train (262144) -- the full capacity of the model will not be utilized
srv    load_model: initializing slots, n_slots = 4
srv  llama_server: model loaded
srv  llama_server: server is listening on http://127.0.0.1:19554
# 12:57 · chat: “Compare Apple, Microsoft and NVIDIA over the last six months.”
slot print_timing: id  1 | task 5073 | prompt eval time =   35996.44 ms / 10516 tokens (    3.42 ms per token,   292.14 tokens per second)
slot print_timing: id  1 | task 5073 |        eval time =    5903.65 ms /    62 tokens (   95.22 ms per token,    10.50 tokens per second)
slot print_timing: id  1 | task 5073 |       total time =   41900.08 ms / 10578 tokens
# 13:05 · news: classifying a headline
slot print_timing: id  3 | task 11618 | prompt eval time =     748.55 ms /   189 tokens (    3.96 ms per token,   252.49 tokens per second)
slot print_timing: id  3 | task 11618 |        eval time =    2753.95 ms /    52 tokens (   52.96 ms per token,    18.88 tokens per second)
slot print_timing: id  3 | task 11618 |       total time =    3502.50 ms /   241 tokens
# 13:05 · news: a longer article
slot print_timing: id  2 | task 11731 | prompt eval time =    3265.84 ms /  1186 tokens (    2.75 ms per token,   363.15 tokens per second)
slot print_timing: id  2 | task 11731 |        eval time =     486.68 ms /    10 tokens (   48.67 ms per token,    20.55 tokens per second)
slot print_timing: id  2 | task 11731 |       total time =    3752.52 ms /  1196 tokens
Try LONDON5 free for 60 days1
Everything above, on your own Mac. Create your London5 account with your email, and we’ll email you a code to download the app. Requires macOS 14 Sonoma or later; Apple silicon recommended.
Try it free for macOS- Cloud AI and data providers you choose may charge you separately. London5 charges no per-trade or performance fees.
- Simulations run on paper capital. A result on past prices doesn't tell you what comes next, and it isn't a recommendation.